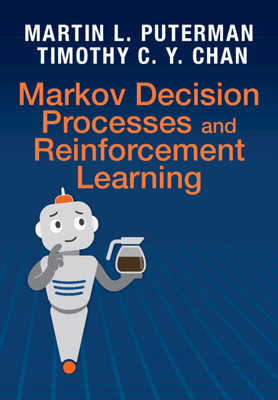
Markov Decision Processes and Reinforcement Learning
暫譯: 馬可夫決策過程與強化學習
Puterman, Martin L., Chan, Timothy C. Y.
- 出版商: Cambridge
- 出版日期: 2026-12-10
- 售價: $5,930
- 貴賓價: 9.5 折 $5,633
- 語言: 英文
- 頁數: 500
- 裝訂: Hardcover - also called cloth, retail trade, or trade
- ISBN: 1009098411
- ISBN-13: 9781009098410
-
相關分類:
Reinforcement、機率統計學 Probability-and-statistics
海外代購書籍(需單獨結帳)
相關主題

商品描述
This book offers a comprehensive introduction to Markov decision process and reinforcement learning fundamentals using common mathematical notation and language. Its goal is to provide a solid foundation that enables readers to engage meaningfully with these rapidly evolving fields. Topics covered include finite and infinite horizon models, partially observable models, value function approximation, simulation-based methods, Monte Carlo methods, and Q-learning. Rigorous mathematical concepts and algorithmic developments are supported by numerous worked examples. As an up-to-date successor to Martin L. Puterman's influential 1994 textbook, this volume assumes familiarity with probability, mathematical notation, and proof techniques. It is ideally suited for students, researchers, and professionals in operations research, computer science, engineering, and economics.
本書以通用的數學符號與語言,全面介紹 Markov decision process(馬可夫決策過程)與 reinforcement learning(強化學習)的基礎。本書旨在提供紮實的基礎,使讀者能夠深入理解並有效參與這些快速發展的領域。
涵蓋主題包括有限與無限時間範圍模型、部分可觀測模型、價值函數近似、基於模擬的方法、Monte Carlo 方法,以及 Q-learning。嚴謹的數學概念與演算法發展,皆搭配大量完整的實作範例加以說明。
本書是 Martin L. Puterman 於 1994 年出版之重要教科書的最新後續著作,讀者需具備機率、數學符號與證明技巧等基礎知識。本書非常適合運籌研究、電腦科學、工程與經濟學領域的學生、研究人員及專業人士閱讀。
以上中文內容由 AI 翻譯